How to use LM Studio
Run AI models on your own computer. The app takes minutes to install, and a few settings decide whether it runs well and stays private.
The short version
- Check your machine: an Apple Silicon Mac on macOS 14 or newer, or a Windows PC with AVX2 and ideally 16GB of RAM.
- Download a model that fits comfortably in your available memory.
- Set GPU Offload as high as it will load, and size Context Length to the job.
- Turn on Require Authentication before letting anything else on your network use the server.
- Your appChat window, editor plugin or script
- Local server
localhost:1234 - Loaded modelHeld in memory
- Your hardwareGPU, then CPU
At a glance
- What it is
- A desktop app and runtime for local AI models
- Runs on
- Mac, Windows, Linux
- Memory
- 16GB+ recommended
- API address
localhost:1234/v1- API password
- Off by default
- Offline
- Yes, once a model is downloaded
Official links
Is LM Studio right for me?
Good fit if
- You want chats and documents to stay on your own machine
- You are building against an OpenAI-style API and want a local target
- You want to compare models on your own hardware
- You work with unreliable internet, or none at all
Look elsewhere if
- You need top-tier model quality on a machine with modest memory
- You use an Intel Mac, which is not supported
- You want a shared team server without managing tokens and network access
- You expect private to mean correct: a local model can still be wrong
How do I run my first model?
Four steps, from installing the app to your first answer.
1Install LM Studio
Get it from the official download page and open it. If your computer is older, check the requirements first.
2Download a model
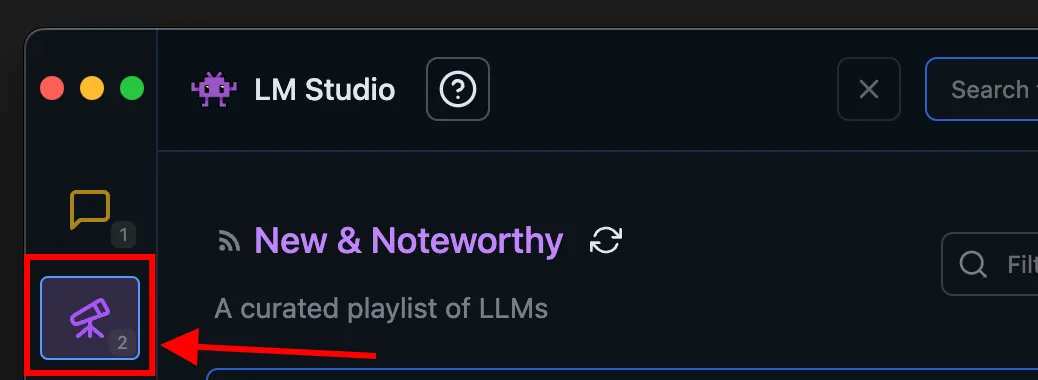
Open the Discover tab, or press Ctrl+2 on Windows and Linux or ⌘+2 on Mac. Pick a curated model or search by name. You can even paste a full Hugging Face URL.
Which download option? Names like Q4_K_M and Q8_0 are the same model at different levels of compression. Lower numbers mean a smaller file and some loss of quality. LM Studio suggests a 4-bit option or higher if your machine can run it.
3Load it into memory
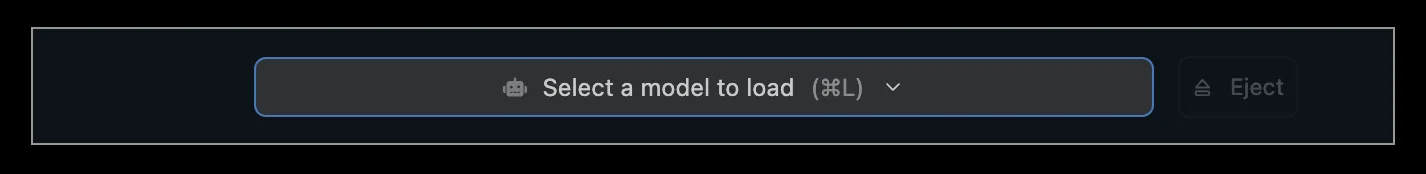
Go to the Chat tab, open the model loader at the top and select your model. Loading sets aside memory for the model, so this is the step that can fail if the model is too big.
4Start chatting
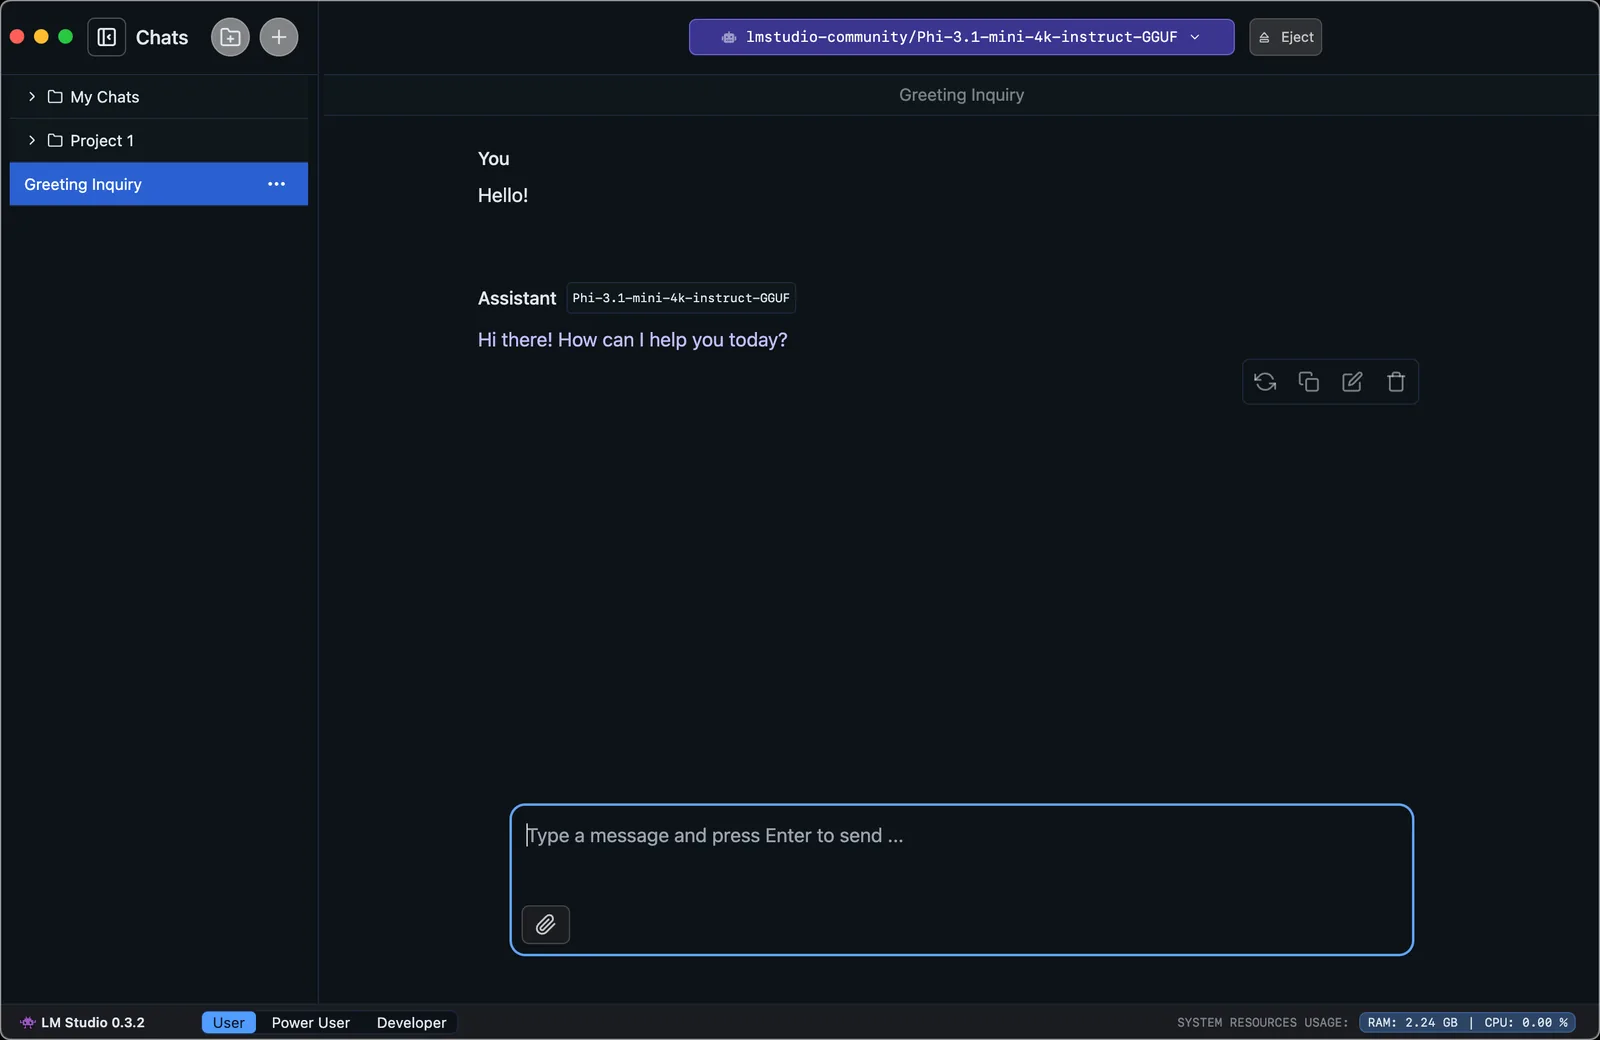
 Watch: Run LLMs Locally with LM Studio: Install, Models, API ServerIndependent tutorial by Tech with Monir, not made by the vendor. Screens may differ from the current version.
What is LM Studio Bionic?
If the website looks different from the tutorials you've seen, this is why. LM Studio now leads with Bionic, its agent for open models.
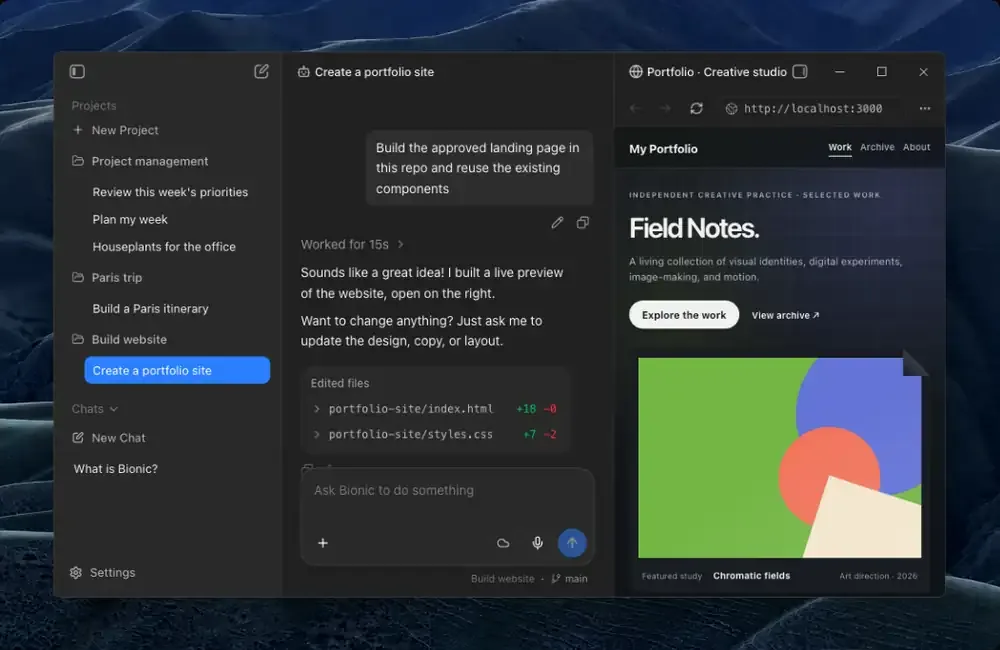
LM Studio describes Bionic as natively local, powered by the LM Studio runtime with MLX and llama.cpp underneath. It also offers cloud services, which it says are Zero Data Retention. So check whether you are running a model locally or through their cloud, because that decides where your data goes.
The rest of this guide covers the foundation everything runs on: the runtime, its settings, the local server and the lms command line.
Will it run on my machine?
The hard requirements are short. The real limit is how much memory your chosen model needs.
| Platform | You need | Memory | Watch out for |
|---|---|---|---|
| macOS | Apple Silicon, macOS 14.0+ | 16GB+ recommended | Intel Macs aren't supported. 8GB Macs may work with small models. |
| Windows | x64 with AVX2, or Snapdragon X Elite | 16GB+ RAM, 4GB+ VRAM recommended | Older x64 CPUs without AVX2 won't run it. |
| Linux | x64 or ARM64, Ubuntu 20.04+ | Not stated | AppImage only. Ubuntu newer than 22 is "not well tested". |
Rule of thumb, not an LM Studio figure: treat a model's file size as the minimum memory it needs, then leave room for context and your other apps. If a model only just fits, choose a smaller one. On a Mac, your browser and editor compete for the same memory.
Which settings matter?
Two sliders explain most complaints about slow or forgetful models. Here's where they are.
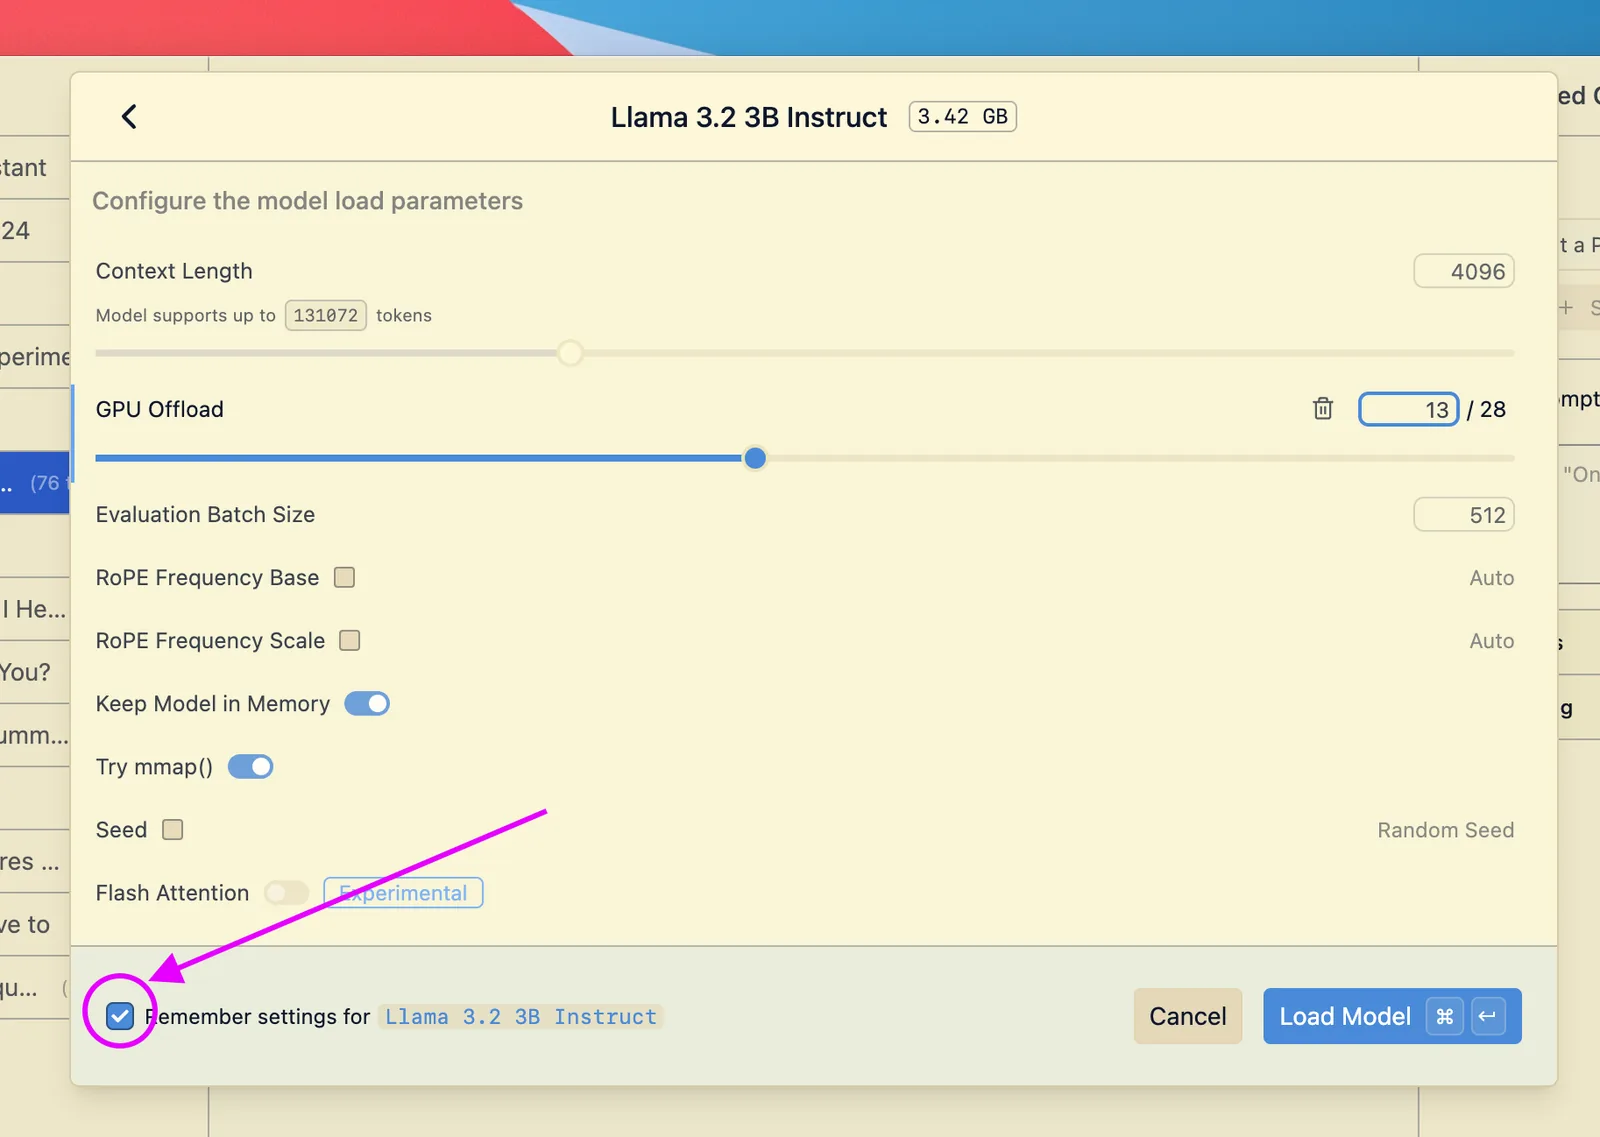
| Setting | What it controls | How to choose |
|---|---|---|
| GPU Offload | How much of the model runs on your GPU | Start at the maximum. Lower it only if loading fails or the machine becomes unstable. |
| Context Length | The model's working memory, in tokens | Size it to the job. One token is about ¾ of a word, so 8,192 tokens is roughly 6,000 words. More context uses more memory. |
| Flash Attention | An option marked Experimental in this screenshot | Test it on your own prompts rather than assuming it helps. |
To see this dialog when you load a model, tick the checkbox in the model picker or hold Option.
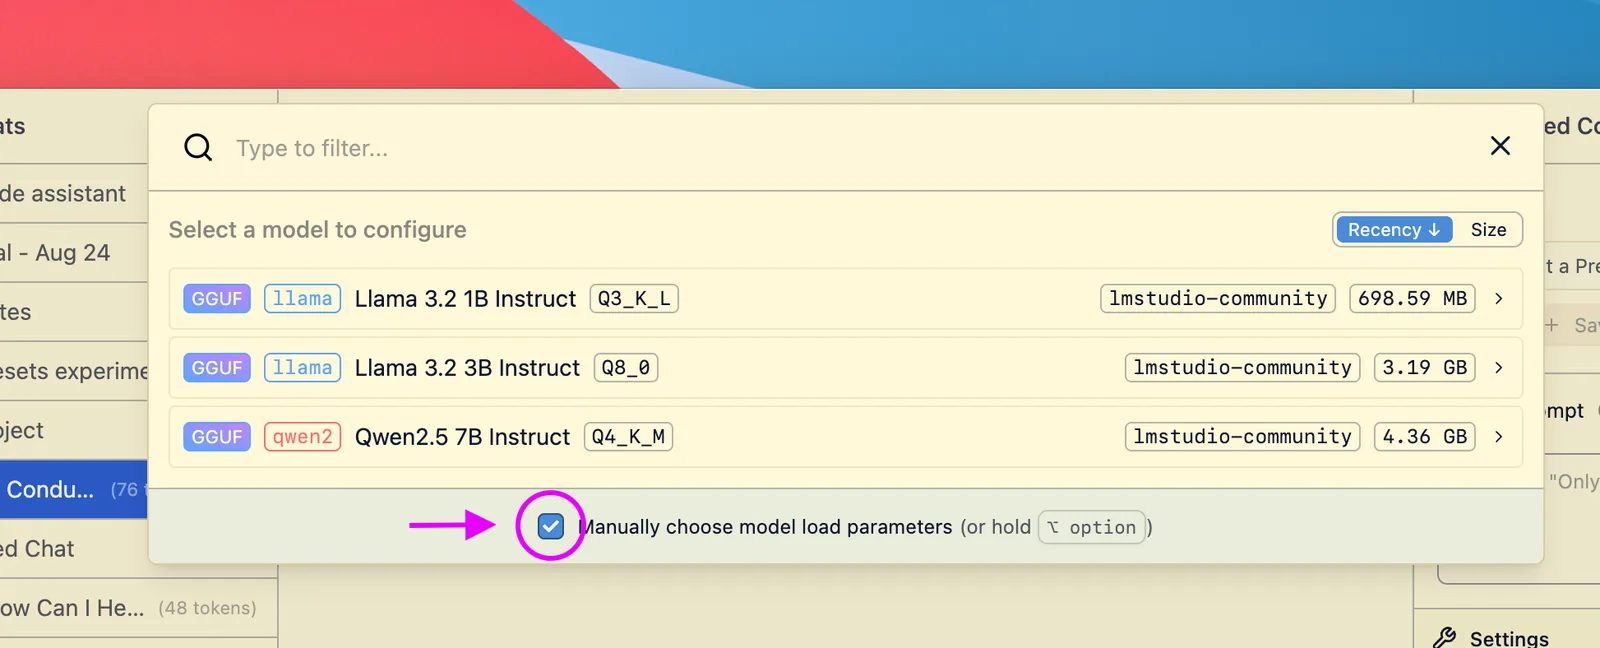
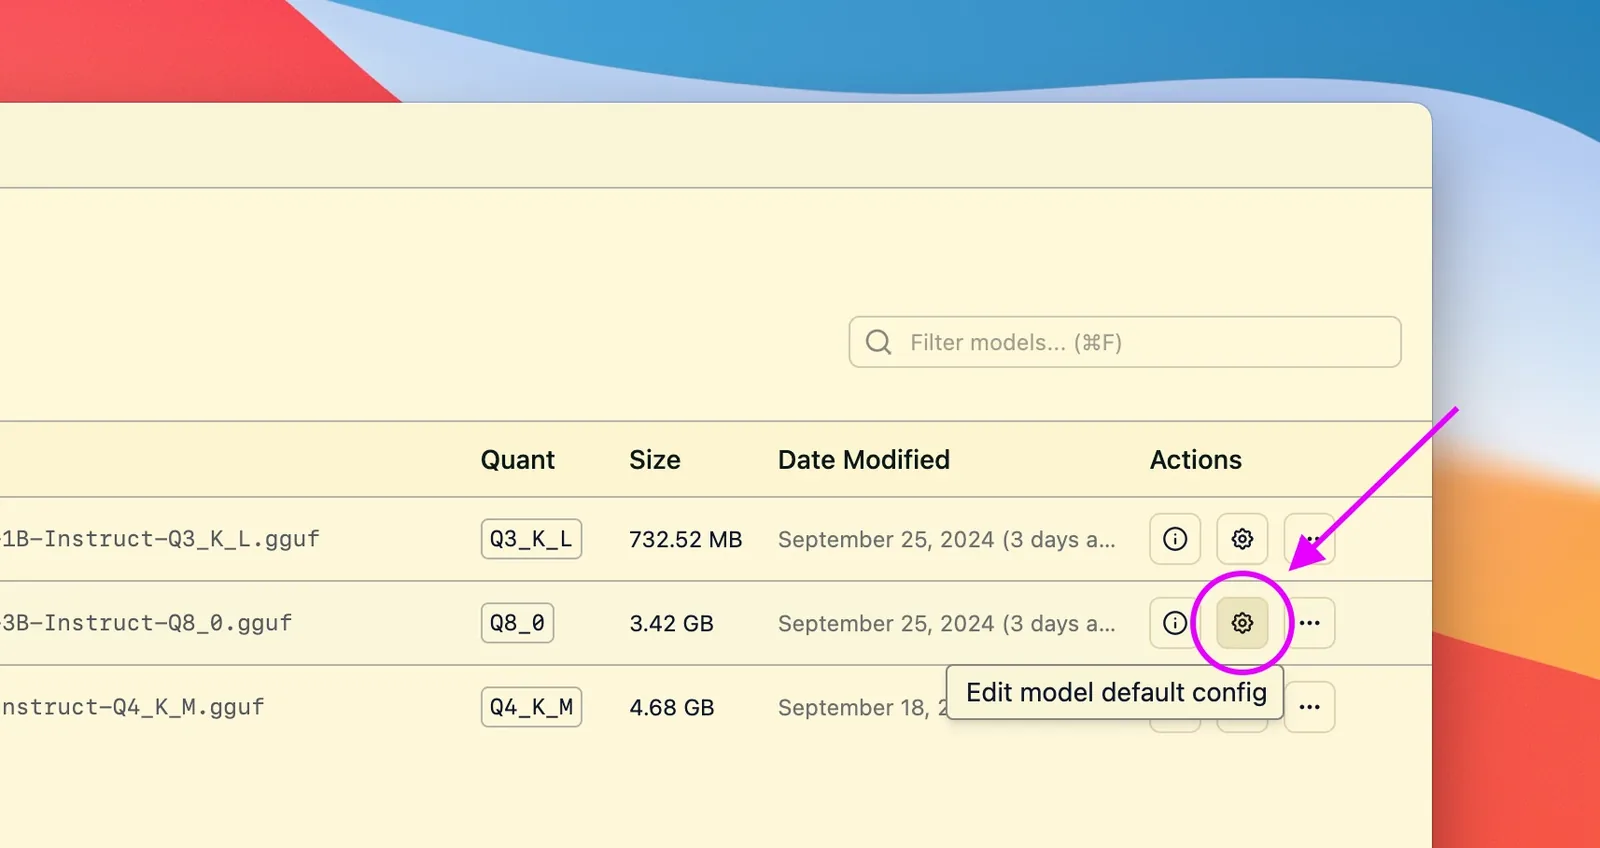
Save your choices once. Tick Remember settings when you load a model, or set defaults from My Models with the gear icon. LM Studio applies them whenever that model loads, including through lms load.
How do I use it as an API?
Start the server from the Developer tab or the command line. Existing OpenAI code usually needs only a new base URL.
from openai import OpenAI

# Authentication is off by default, but the OpenAI client still expects a key.
client = OpenAI(base_url="http://localhost:1234/v1", api_key="not-needed-locally")

reply = client.chat.completions.create(
    model="my-model-name",
    messages=[{"role": "user", "content": "Summarize this ticket in one sentence."}],
)
print(reply.choices[0].message.content)
LM Studio also documents an Anthropic-compatible Messages route and its own REST API. For a machine with nobody at the screen, the lms command line covers everything. Run the desktop app at least once first.
lms daemon up        # start the headless daemon
lms get <model>      # search for and download a model
lms load <model> --identifier="my-model-name" --context-length=8192 --gpu=max --ttl 3600
lms server start     # start the API server
lms ps               # see what's loaded
lms log stream       # watch requests and responses
Always set --identifier. It gives your code a stable name, so you can swap the underlying model without changing your application.
Why do models keep reloading?
How a model got into memory decides when it leaves.
| Loaded automatically on first request | Loaded with lms load | |
|---|---|---|
| Idle timeout | 60 minutes by default | None. It stays until you unload it. |
| Change the timeout | Send "ttl" in seconds with the first request | Add --ttl <seconds> |
| Auto-Evict applies? | Yes, on by default | No |
| Models kept at once | One, with Auto-Evict on | As many as you load |
If two apps ask for different models, Auto-Evict keeps swapping them, and each swap is a full reload. Load both with lms load if you have the memory, or turn Auto-Evict off in the Developer tab's Server Settings.
If your memory seems to have vanished, a model you loaded weeks ago may still be there. lms ps shows it, and lms unload --all clears it.
Example output from LM Studio's docs
$ lms ps

   LOADED MODELS
Identifier: unsloth/deepseek-r1-distill-qwen-1.5b
  • Type:  LLM
  • Path: unsloth/DeepSeek-R1-Distill-Qwen-1.5B-GGUF/DeepSeek-R1-Distill-Qwen-1.5B-Q4_K_M.gguf
  • Size: 1.12 GB
  • Architecture: Qwen2
How do I keep it secure?
Local is only private while the server stays local. By default, the API doesn't ask for a password.
- Keep Serve on Local Network off unless another device needs access.
- Turn on Require Authentication in Server Settings before enabling network access. This needs LM Studio 0.4.0 or newer.
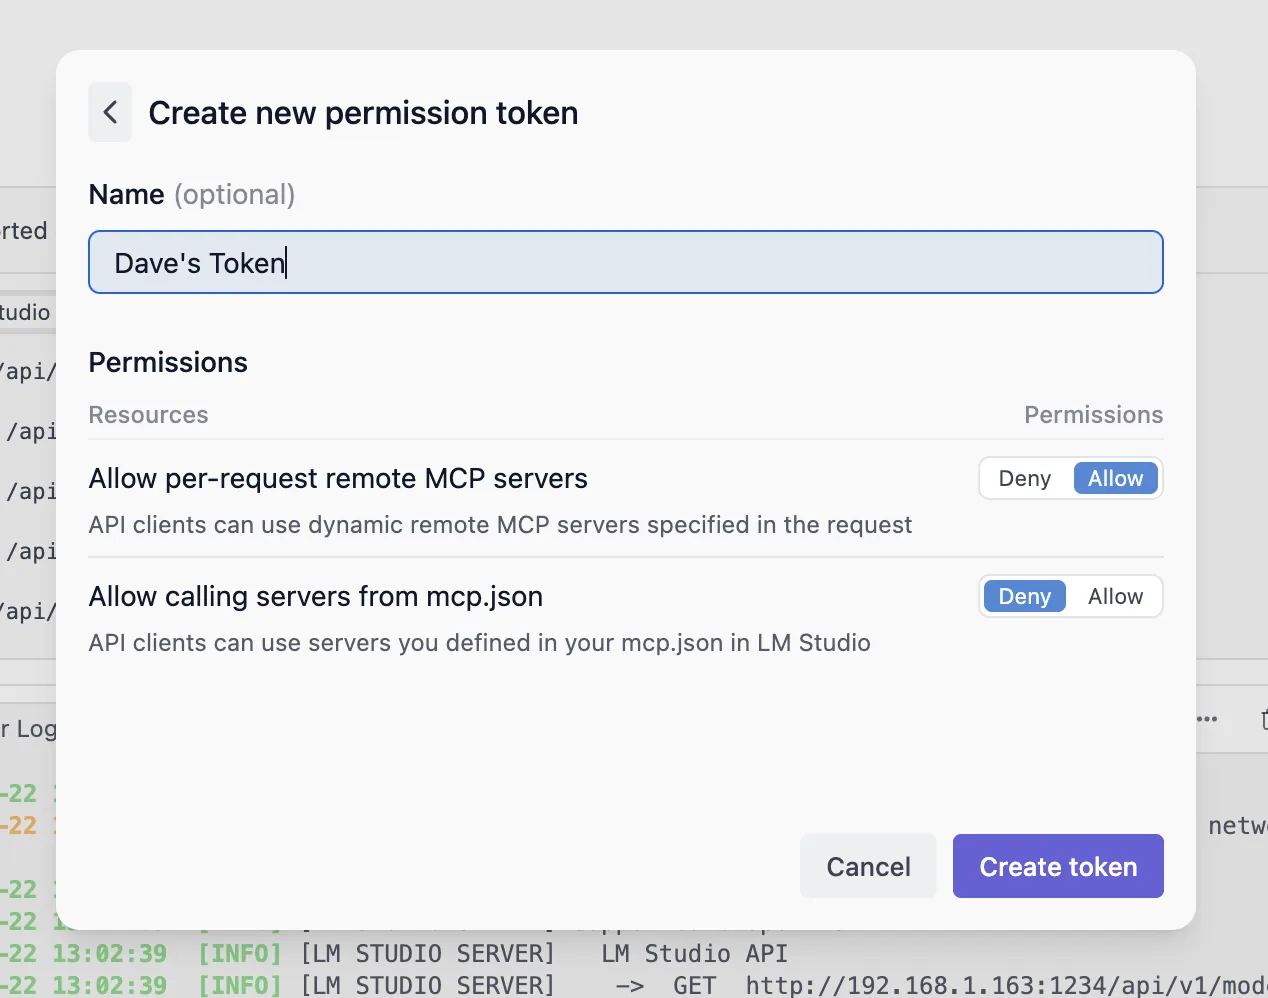
- Create a separate token for each client under Manage Tokens, and copy it straight away. It won't be shown again.
- Enable CORS only when a browser app on another origin has to call the server.
- Leave Allow calling servers from mcp.json off unless you need it. LM Studio warns it can be a security risk.
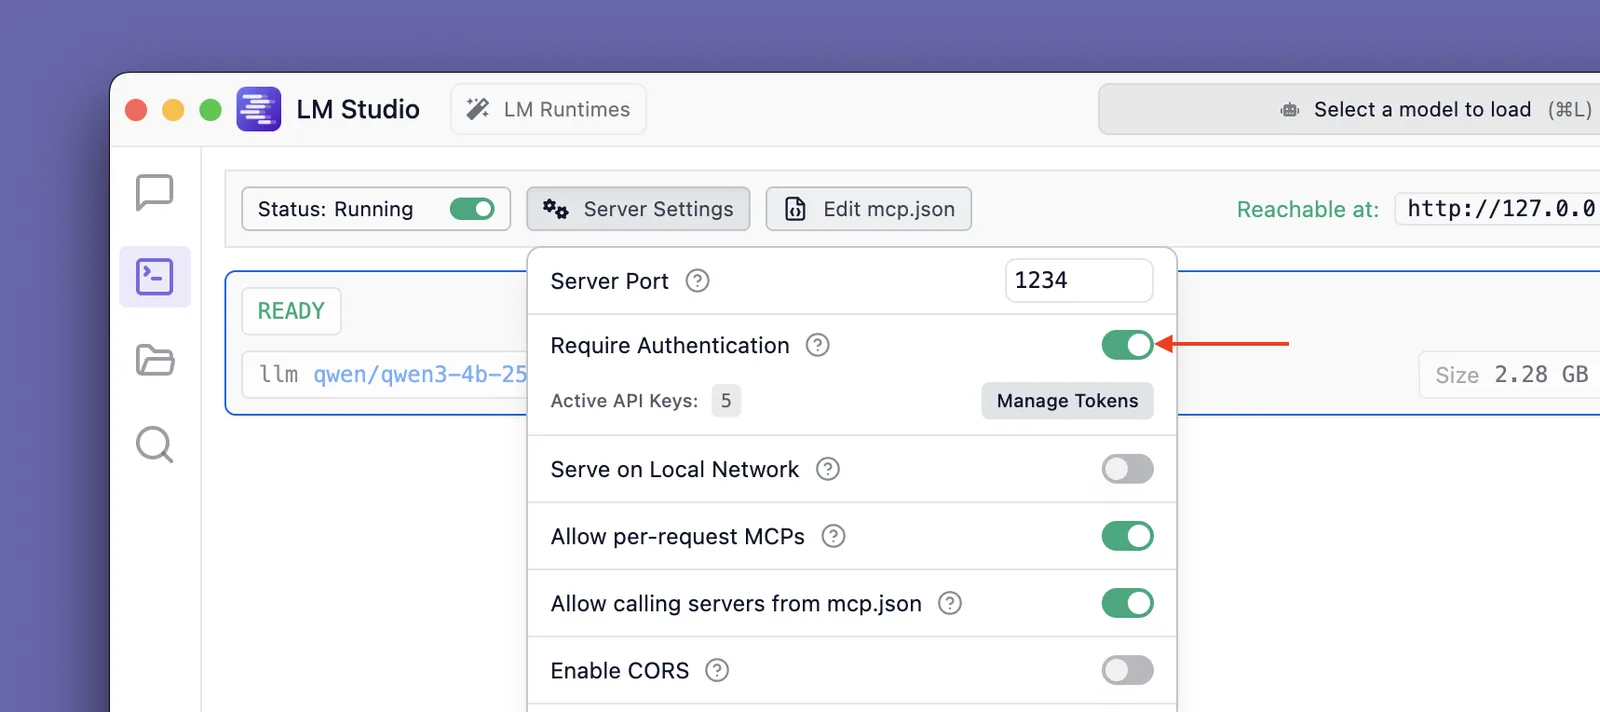
Clients then send the header Authorization: Bearer <token>.
Limit what each token can do. When you create one, you can allow or deny MCP access per token, so a client doesn't get more than it needs.
Can it read my documents?
Yes, .docx, .pdf and .txt files. But short and long files are handled differently, which explains most inconsistent answers.
Getting better answers from long files: use the words you expect to appear in the passage. "Termination notice period, days, written notice" gives retrieval more to match than "what happens if we leave?" Raising Context Length can also let a file be read in full.
Does it work offline?
Yes, once you have a model. LM Studio says your chats and documents stay on your device.
Works offline
- Chatting with downloaded models
- Chatting with documents
- Running the local server
Needs a connection
- Searching for models
- Downloading models
- Downloading runtimes
- Checking for app updates
For a machine that must stay offline, you can sideload models. Put the file in ~/.lmstudio/models/<publisher>/<model>/, or try the experimental lms import <path/to/model.gguf>.
Hidden tips
Details that are easy to miss, each with the official page that backs it up.
-
Paste a Hugging Face URL into search
Discover's search accepts keywords, a
Download an LLMuser/modelstring or a full Hugging Face URL. -
A manual load never times out
Models loaded with
Idle TTL and Auto-Evictlms loadhave no default timeout. On a shared machine, always pass--ttl. -
Set the timeout from your app
Send
Idle TTL and Auto-Evict"ttl": 300with the request that triggers a load, and the model unloads after 5 idle minutes. It suits occasional batch jobs. -
Saved defaults reach the command line
Defaults set in My Models also apply to
Per-model defaultslms load, so a script can inherit a setup you tuned by hand. -
Limit how much memory auto-loading can use
"Only Keep Last JIT Loaded Model" and "Auto Unload Unused JIT Models" are separate server switches.
Server settings -
Per-request MCP is remote only
"Allow per-request MCPs" works for that request only, and only with remote servers. Local tools won't work this way.
Server settings -
See what your app really sends
lms CLIlms log streamshows requests and responses live, so you can tell whether a problem is your prompt, your client or the model.
LM Studio FAQ
Is LM Studio really private?
LM Studio says what you enter when chatting with a downloaded model, and documents you add, stay on your device. It still makes network requests for model search, downloads, catalog details and update checks. Its cloud services are separate, and it says they are Zero Data Retention. If you enable network serving without authentication, other devices can reach the API.
How much RAM do I need for LM Studio?
LM Studio recommends 16GB or more on macOS and at least 16GB on Windows, plus at least 4GB of dedicated VRAM on Windows. On an 8GB Mac it suggests sticking to smaller models and modest context sizes. What you really need depends on the model.
Does LM Studio work on Intel Macs?
No. The macOS version requires Apple Silicon and macOS 14.0 or newer.
What is LM Studio's default API address?
The docs use http://localhost:1234 in their examples, with OpenAI-compatible routes under /v1, so chat completions are at http://localhost:1234/v1/chat/completions. You can change the port in Server Settings.
Why does my model keep reloading?
With Auto-Evict on, a newly auto-loaded model unloads the previous one, so apps requesting different models keep displacing each other. Load the models with lms load, or turn Auto-Evict off in Server Settings.
Can I run LM Studio without the desktop interface?
Yes. The lms command line includes a headless daemon (lms daemon up) and commands to download models, load them and start the server. The docs say to run LM Studio at least once first.
What is the difference between LM Studio and Bionic?
LM Studio's site describes Bionic as its agent for open models, built for documents, code and computer tasks and powered by the LM Studio runtime. The runtime, local server and lms command line covered here are the foundation it runs on.
Sources
Facts checked 4 November 2026. Products change, so confirm anything important on the official pages.