How to use TypeSafe AI
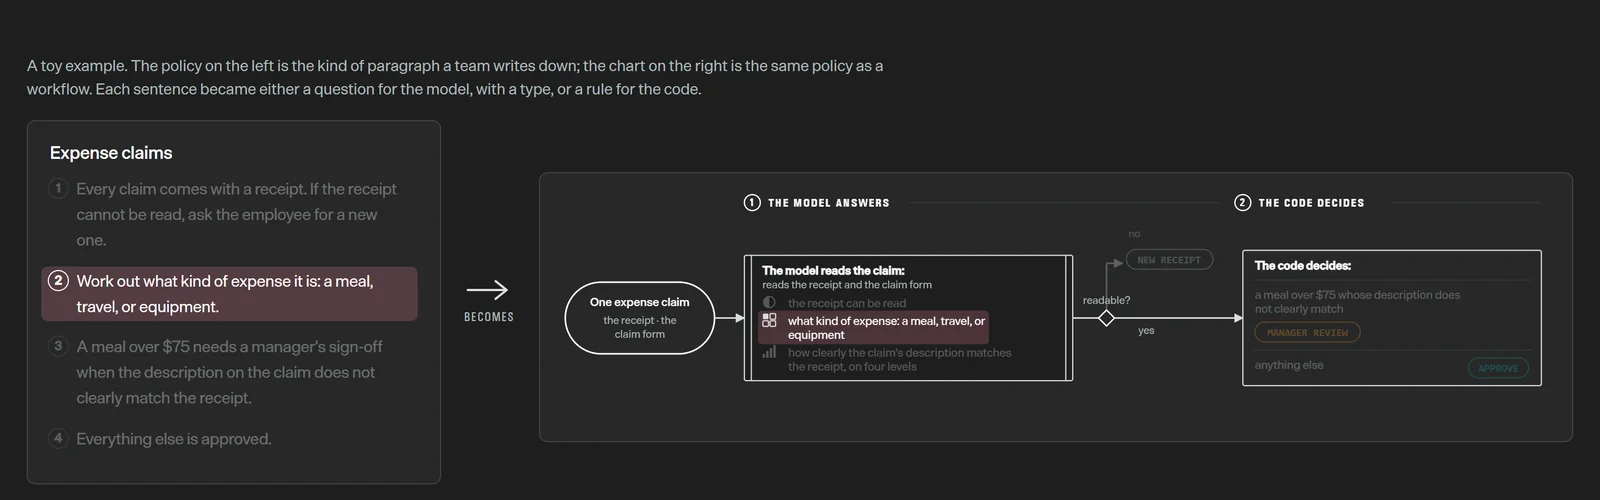
TypeSafe AI sells Jev, a model that doesn't write text. You send it some data and a set of typed questions, and it returns choices, levels or yes-no probabilities that your code can act on. It's cheap and fast, but not a substitute for a chat model, and it can still be wrong.
The short version
- Get a key from the TypeSafe console, run
pip install typesafe-sdk, and callclient.system_one()with astateand somequestions. - Questions come in three everyday types: Choice picks an option, Score finds a level, and Noul returns a yes probability from 0 to 1.
- Act on the probability, not on
confidence. TypeSafe suggests 0.7 and 0.3 as starting Noul thresholds, with a separate path for the band between them. - Keep math, counting and date comparison in your code. TypeSafe's own docs say Jev is unreliable at them.
At a glance
- What it is
- A typed decision model, not a chatbot
- Model
jev-1.14.0, alsojev-latest- Price
- $0.042 per million input tokens, with free output
- Speed
- About 100 ms for most calls, says TypeSafe
- Context
- 64k per request, 32k per question
- Input
- Text and JSON. Images are preview only.
Official links
Is TypeSafe AI right for me?
Good fit if
- You need classification, routing or scoring inside software, at high volume
- You want typed answers without writing parsers for model output
- You want a real-time check, such as a guardrail, in a user-facing request path
- You're comfortable tuning thresholds and testing on your own data
Look elsewhere if
- You need generated text, code or summaries, because Jev doesn't produce any
- You need arithmetic, dates or counts, which TypeSafe says to keep in code
- You work mainly in languages other than English and can't test them first
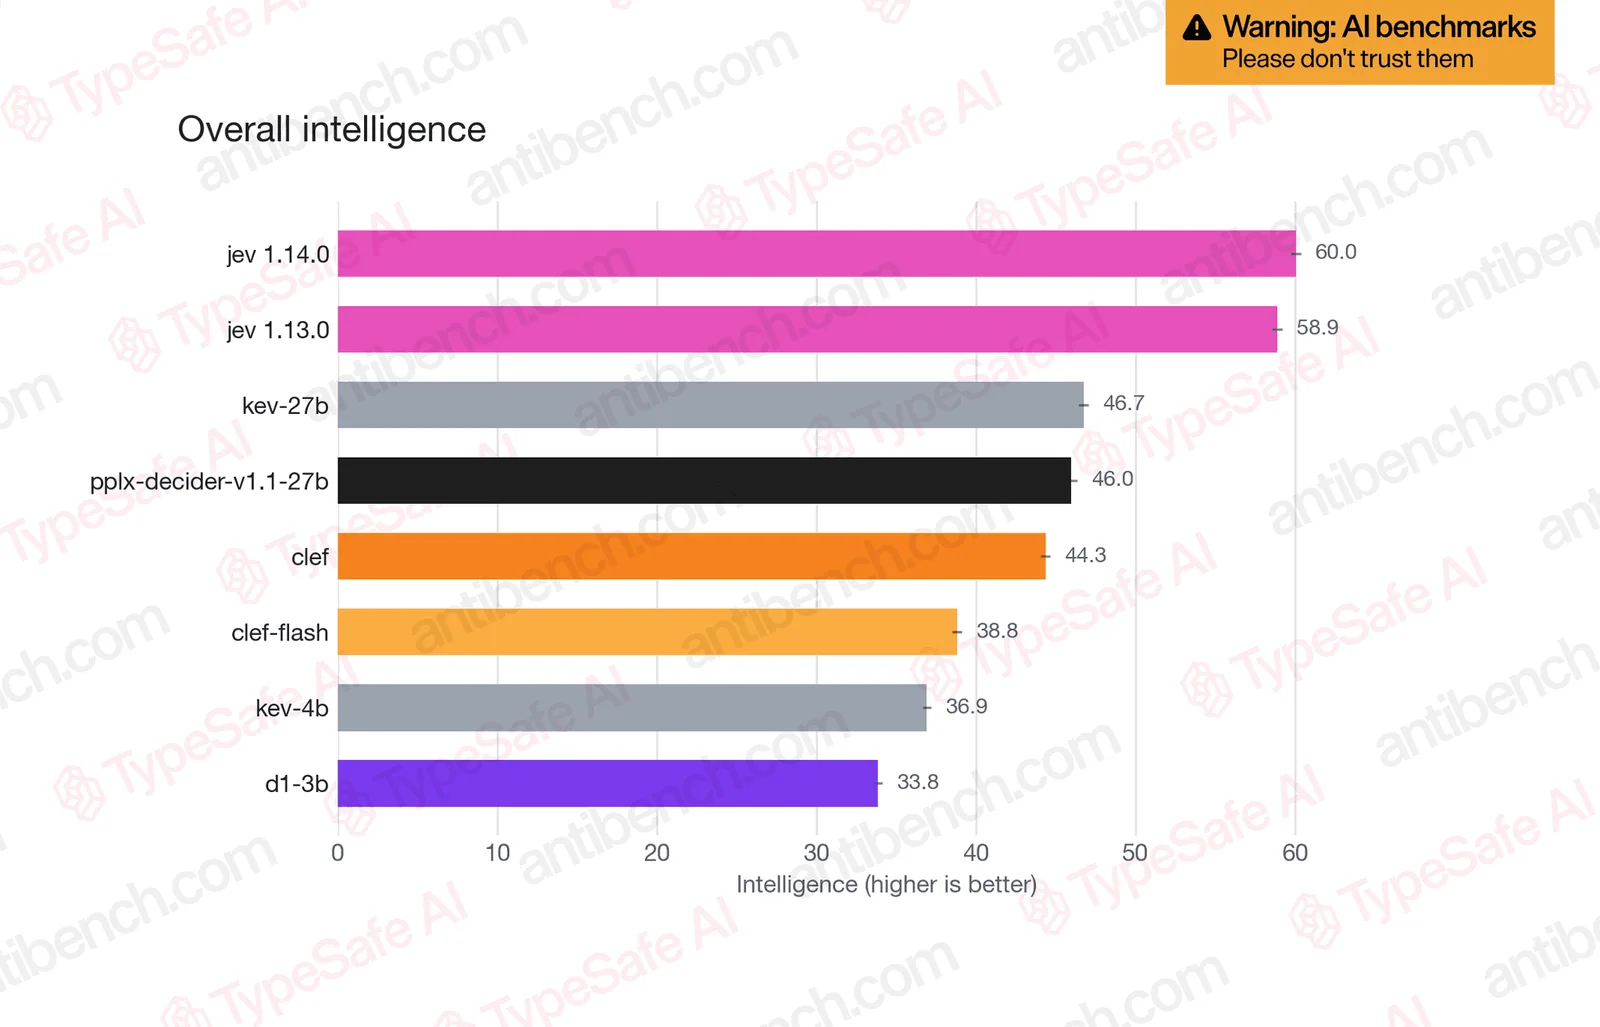
- You need the highest accuracy on hard decisions, where its own chart shows larger models ahead
How do I make my first Jev call?
A request has two main parts: the state, which is what to judge, and questions, which is what you want to know about it. All questions run at once.
From TypeSafe's quickstart. Needs Python 3.10 or later.
# python3 -m venv .venv && .venv/bin/pip install typesafe-sdk
# export TYPESAFE_API_KEY="your-api-key"
from typesafe_sdk import Choice, Noul, Score, TypeSafeClient

ticket = "Our API integration started returning 500 errors on every request about 20 minutes ago, and we can't process any customer orders until this is fixed."

with TypeSafeClient(model="jev-latest") as client:
    response = client.system_one(
        state=ticket,
        questions={
            "department": Choice(
                instructions="Which team should handle this",
                criteria={
                    "billing": "Payment or subscription issues",
                    "technical": "Bugs or integration problems",
                    "sales": "Pricing or account questions",
                },
            ),
            "frustration": Score(
                instructions="How frustrated the customer appears",
                criteria=["Calm, just stating facts", "Frustrated but civil", "Very angry, strong language"],
            ),
            "is_urgent": Noul(instructions="The message conveys urgency or time-sensitivity"),
        },
    )

print(response.choices["department"].choice)
print(response.scores["frustration"].score)
print(response.nouls["is_urgent"].noul)
The same idea over HTTP. Node needs 20 or later, with @typesafe-ai/sdk.
curl https://api.typesafe.ai/v1/systemone \
  -H "Authorization: Bearer $TYPESAFE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "jev-latest",
    "state": "I was charged twice for my subscription this month.",
    "questions": {
      "billing": { "type": "noul", "instructions": "Is this message about billing?" }
    }
  }'
# The docs' sample response: "answers": {"billing": {"type": "noul", "noul": 0.98}}
Worth knowing from the start
- Question IDs are for your code and aren't sent to the model
- So put the full question in
instructions - Option names and descriptions are both sent
- Use an object as
statewhen you have several fields
What couldn't be checked
- The console blocked automated readers on 5 November 2026
- So sign-up steps and any free credit weren't verified
- TypeSafe's launch post said early access, and its site now says Create Account
- Check for a waitlist or starting credit when you sign up
 Watch: Asking JEV's Creator the Hard Questions About This Hot New AI ModelIndependent tutorial by The TWIML AI Podcast with Sam Charrington, not made by the vendor. Screens may differ from the current version.
This interview comes from an independent podcast. TypeSafe's own demo videos are on Vimeo and embedded on its blog.
Should I use Choice, Score or Noul?
Pick the one your code can act on directly. A Choice maps to code paths, a Score to a threshold, and a Noul to an if.
| Type | Use it when | You get back | Example |
|---|---|---|---|
| Choice | One of a known set, with no order | choice, probabilities, confidence | Which team handles this? |
| Score | A position on a scale you can describe | score, legend, probabilities, confidence | How severe is this bug? |
| Noul | A clean yes or no | noul, from 0 to 1 | Did they ask for a refund? |
| Box | Where something is in an image. Preview only. | box, confidence | Where is the logo? |
A Choice always picks something. Even if nothing fits, you'll get an answer. TypeSafe advises against adding an "other" option, which it says competes with your real ones for probability. Add a companion Noul instead, which asks whether any option fits, and act on the Choice only if that says yes.
Companion Noul pattern. Illustrative, based on TypeSafe's docs.
questions = {
    "meeting_type": Choice(
        instructions="What type of meeting is this?",
        criteria={"standup": "...", "planning": "...", "retrospective": "..."},
    ),
    # The companion: act on meeting_type only if this is high
    "any_type_fits": Noul(
        instructions="Is this meeting a standup, a planning session or a retrospective?",
    ),
}
A Noul of 0.5 isn't a medium. TypeSafe warns that for "Is this candidate strong in Python?", 0.5 means yes and no are equally likely, not medium skill. To measure skill, use a Score with defined levels. For a decision, ask a checkable question, such as whether the resume states they've used Python at work.
Decompose big judgments. Don't ask "rate this startup pitch". Ask about market size, technical feasibility and differentiation separately, then weight the answers in code. When your priorities shift, you change a number, and your prompts stay stable.
Which number should I act on?
Usually the probability, not confidence. TypeSafe says confidence measures how concentrated an answer is, not the chance that it's correct.
| Type | Threshold on | Why |
|---|---|---|
| Noul | The noul value. Try above 0.7 as yes, and below 0.3 as no. | It's already the probability. Give the middle its own outcome. |
| Choice | probabilities[choice] | It's the chance that the option is correct |
| Score, one level matters | That level's probability | A position between levels can hide a split answer |
| Score, is it settled at all? | confidence first, then route on the score | It catches answers spread across distant levels |
| Just need the best option | Nothing. Take choice. | No threshold needed |
| Number of options | Top probability | confidence |
|---|---|---|
| 2 | 0.75 | 0.5 |
| 3 | 0.67 | 0.5 |
| 10 | 0.55 | 0.5 |
Risk-scaled thresholds, adapted from TypeSafe's example to use the probability
action = response.answers["action"]
p = action.probabilities[action.choice]

if p < 0.5:
    route_to_human(message)        # the model really is unsure
elif action.choice == "check_balance":
    show_balance(account_id)       # low stakes, easy to undo
elif action.choice == "approve_transfer" and p > 0.9:
    confirm_then_execute(account_id)  # high stakes, still confirm
else:
    ask_user_to_confirm(account_id)
Keep questions and thresholds in one file. TypeSafe's agent-skill page says those are the most important things to review, and that agents "aren't great at writing questions". Treat them like the business rules they are.
How cheap and fast is Jev really?
The price is simple: $0.042 per million input tokens, with free output. TypeSafe's bigger comparison numbers come with caveats that it states itself.
| Item | Value |
|---|---|
| Input | $0.042 per million tokens, or $42 per billion |
| Output | Free |
| Normal context | 64k per request, and 32k per question |
| Long context | 262k with TypeSafe-Danger-Zone-Long-Context: true. Same token price, but slower and less accurate. |
| Number of questions | No separate limit, as long as the request fits |
| Rate limits | Set per organization, in tokens and requests per second. Over limit returns 429. |
| Response time | 70 to 500 ms in the launch post, and about 100 ms for most calls in the docs |
Rough cost. A 1,000-token request is about $0.000042, so a million such requests is about $42. That's this guide's arithmetic. Questions count toward input, and TypeSafe's sample shows input_tokens and output_tokens in usage.
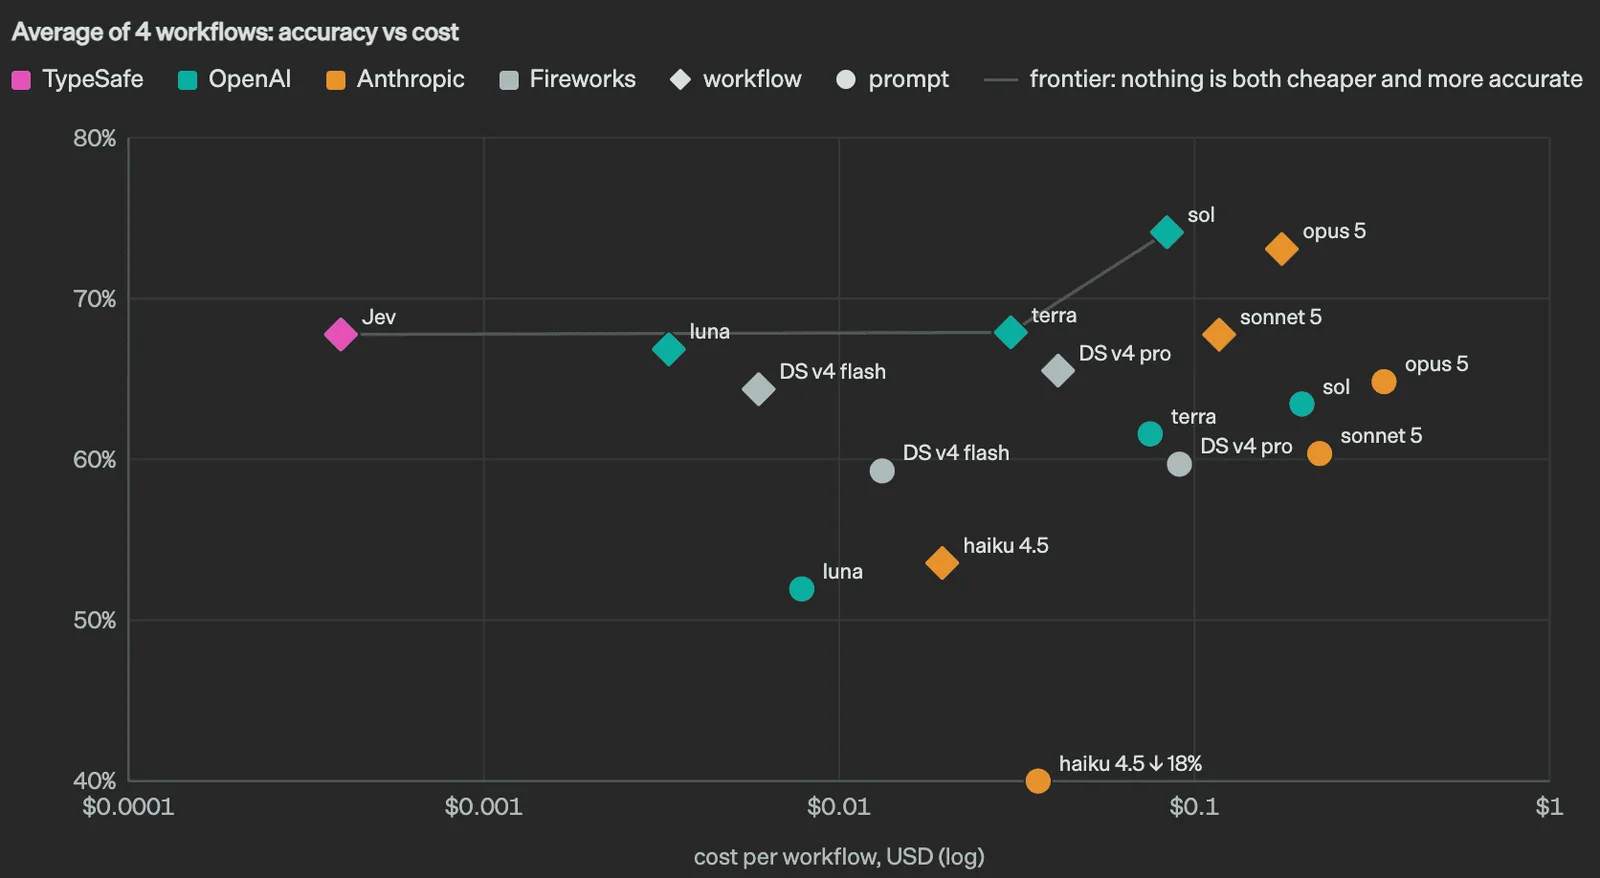
| Model | Accuracy | Cost per case | Time per case |
|---|---|---|---|
| Jev | 67.8% | $0.0004 | 0.4 s |
| GPT-5.6 Luna | 66.8% | $0.0033 | 12.9 s |
| GPT-5.6 Terra | 67.9% | $0.0304 | 10.1 s |
| Claude Sonnet 5 | 67.8% | $0.1174 | 78.1 s |
| GPT-5.6 Sol | 74.1% | $0.0836 | 23.3 s |
| Claude Opus 5 | 73.1% | $0.1761 | 37.8 s |
TypeSafe's own caveats on these numbers
- The "193.6x faster, 444.6x cheaper" figures are, it says, "on the higher end of real world gains"
- Its own model team built the workflows, "so some bias could exist"
- Using OpenAI and Anthropic models as reference favors those models, it notes
- For LLMs, it used its own wrapper, which it says tends to be slower and costlier
- Its latest "intelligence" chart is, in its words, "likely biased towards our models"
Can Jev really not hallucinate?
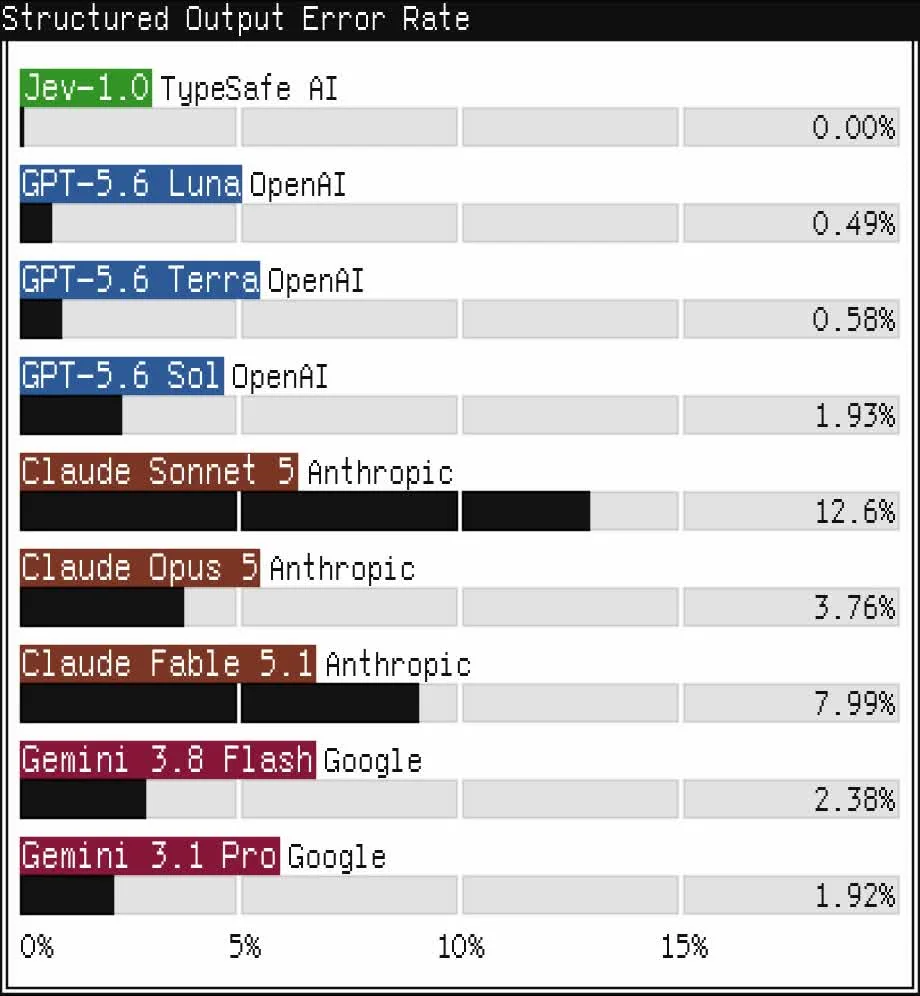
It can't return an option you didn't define. It can still pick the wrong one. TypeSafe's phrase "zero hallucinations" is about the shape of an answer, not whether it's true.
| Failure | What goes wrong | What to do instead |
|---|---|---|
| Literal reading | It answers the words you wrote, not what you meant | Put boundary cases in the criteria |
| Math and counting | "Jev is not a calculator", and counts are unreliable | Do it in code. Ask one question per item, then add up. |
| Dates and times | It reads dates as text, so ordering is unreliable | Extract parts as Choices, and compare in code |
| Indirection | Double negatives and multiple hops cost accuracy | Name the relevant field directly |
| Large state | Unrelated detail acts as a distractor | Filter in code first, or use a Noul for relevance |
| Adversarial content | "State is data, and Jev does not treat it as hostile by default" | Be explicit in criteria, and test edge cases |
| Contradictory criteria | For example, a Noul where true maps to no | Keep instructions and criteria aligned |
| Choice order | Option order can change the answer | Reorder options, and check that the answer holds |
| Generation | It doesn't generate text | Use a generative model |
TypeSafe's pattern for counting: ask per item, and add up in code
from typesafe_sdk import Noul, TypeSafeClient

client = TypeSafeClient(model="jev-latest")
YES = 0.5  # your own threshold
items = ["typesafe", "apple", "california", "banana", "likes", "calibration", "orange", "vertex"]

result = client.system_one(
    {"items": items},
    {f"item_{i}": Noul(instructions=f"Is `items[{i}]` the name of a fruit?") for i in range(len(items))},
)
count = sum(result.nouls[f"item_{i}"].noul > YES for i in range(len(items)))
Treat outside text as hostile yourself. Jev is pitched for guardrails and verification, yet TypeSafe says content written to steer it "can move the answer". Rule of thumb, not a TypeSafe instruction: don't let a single Jev answer on untrusted text trigger a payment, a deletion or an account change.
Language. English is the primary training language and has the best accuracy, says TypeSafe. Others, including CJK scripts, are "handled but not equally well", so test before relying on them. Jev 1.14's main listed improvement is better multilingual support.
Will updates change my results?
They can if you use an alias. jev-latest moves when a new release ships, so pin a version once you've tuned thresholds against it.
| Name | Points to | Use it for |
|---|---|---|
jev-latest | jev-1.14.0 | Prototypes, and the SDK default |
jev-preview | jev-1.14.0, for now | Trying builds ahead of latest |
jev-1.14.0 | Fixed | Production, with tuned thresholds |
jev-1.13.0 | Fixed | Existing tuned systems |
TypeSafe's data statements
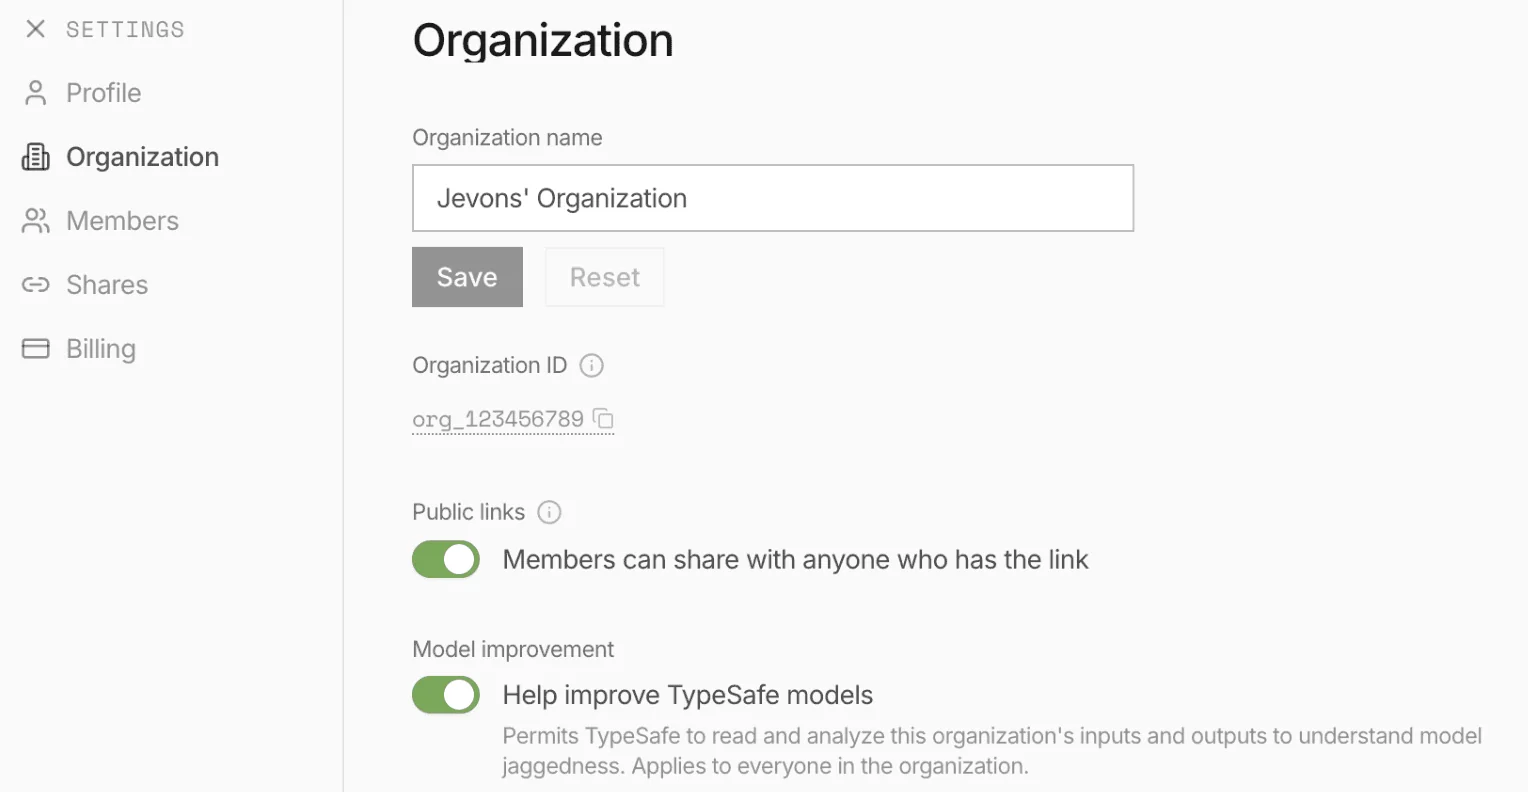
- "Jev is not trained on customer requests or responses"
- Jev isn't fine-tuned per customer, and all accounts use the same weights
- SOC 2 Type II report, by request through its Trust Center
- Zero data retention for enterprise customers
Preview features, on your own risk
- Images need
TypeSafe-Danger-Zone-Images: true - Box needs Jev 1.14 and the same header
- TypeSafe says these aren't "up to our standards" for production
- The models page still lists input as text, which is about the stable path
 Watch: Jev by TypeSafe AI | What is a System-1 Decision Model | CampusXIndependent tutorial by CampusX, not made by the vendor. Screens may differ from the current version.
Can my coding agent build with Jev?
Yes. TypeSafe publishes a skill that gives Claude Code and other agents its API details and patterns. Use it for the plumbing, and review the questions yourself.
From TypeSafe's docs. Pick one method.
# Claude Code
claude plugin marketplace add typesafe-ai/skills
claude plugin install typesafe@typesafe-ai

# Other agents
npx skills add typesafe-ai/skills --skill typesafe-ai
Common problems
- Agent isn't using it? Name it, or run
/typesafe:typesafe-ai. - Agent invents fields? Update the skill, because a stale one can cause that.
- Thresholds everywhere? Often you can just take the top option.
- Routing looks wrong? Check your thresholds, then make questions more specific.
Patterns to look up
- Companion Noul, when a list may not fit
- Composite scoring, for weighted judgments
- Confidence routing and probability routing
- Fan-out, for many questions in one request
A good first use, from TypeSafe. Ask your agent to find "complex parsing or other fragile code" that a judgment could replace, then look at the plan before implementing. If you have an existing LLM app, its cookbook has guardrails and double-checking citations recipes, which add Jev alongside your current model.
Hidden tips
Details that are easy to miss, each with the official page that backs it up.
-
Reorder your options as a test
TypeSafe has seen option order affect some Choice answers. Run the same input with options reversed. If the answer flips, your options need clearer descriptions.
Model jaggedness -
Use names, not hex codes
Jev does better on semantic forms than raw numbers. Convert hex colors or RGB to a name or bucket in code, and ask the model only the judgment part.
Model jaggedness -
Don't interpolate a Score
TypeSafe warns against computing an exact magnitude between two levels. Use the expectation to check a threshold, but don't reconstruct a number from it.
Model jaggedness -
Point at fields by path
Name a state field in backticks, such as
Primitivesorder.charges, when a question concerns one part of it. That removes a hop, which TypeSafe says costs accuracy. -
List your models from the API
ModelsGET /v1/modelsreturns aliases with release dates. Versioned IDs such asjev-1.14.0work even when they aren't in the list. -
SDKs already retry 429s
TypeSafe's client libraries retry rate-limited calls and honor
Modelsretry-after. Only direct HTTP callers need to write that themselves. -
Add questions without side effects
Each question is evaluated independently, so one answer isn't hidden context for another. You can add or remove questions without changing the others' results, says TypeSafe.
Primitives -
Long context isn't free of cost
It's the same token price, but TypeSafe says it's slower and less accurate. Send the header only on requests that need it, and filter your state first when you can.
Models
TypeSafe AI FAQ
What is TypeSafe AI?
A company building System One Models, which make typed decisions for software, rather than writing text. Jev is its first public model, launched on 15 September 2026.
How much does Jev cost?
TypeSafe lists $0.042 per million input tokens, with free output. It says it can't prove the price isn't subsidized, but expects pricing to go down rather than up. Enterprise and higher-limit plans are by contact.
What is a Noul?
TypeSafe's yes-or-no question type. The answer is one number from 0 to 1, which is the probability of yes. There's no separate confidence field.
Is Jev better than GPT or Claude?
For different jobs. TypeSafe's own evals show Jev at similar accuracy to some mid-tier models at far lower cost and time, and behind the largest models on accuracy. It can't write text. Test it on your own data.
Does Jev train on my data?
TypeSafe says Jev isn't trained on customer requests or responses. A separate organization setting lets it read inputs and outputs to find failures. Zero data retention is available for enterprise customers.
Can Jev read images?
Only in preview. Send the TypeSafe-Danger-Zone-Images header. TypeSafe says images and Box questions aren't yet ready for production, and that all models perform worse on images than on text.
Can Jev be tricked by prompt injection?
It can be influenced. TypeSafe says content written to steer the model can move the answer, and that Jev doesn't treat state as hostile by default. Test your integration and don't rely on one answer for risky actions.
Sources
Facts checked 5 November 2026. Products change, so confirm anything important on the official pages.
- TypeSafe docs: Quick start
- TypeSafe docs: Introduction
- Primitives
- Noul
- Choice
- Confidence
- Models
- Model jaggedness
- Model changelog
- State
- How to build with TypeSafe
- Images
- Agent skill
- Cookbooks
- HTTP API reference
- Legal
- Introducing System One Models & Jev
- Jev: For the builders and dreamers
- Workflow evals
- TypeSafe homepage
- TypeSafe for enterprise